
AI business use cases are useful only when they connect a business problem to suitable data, a real workflow, a measurable result and a person who remains accountable. A chatbot, prediction model or AI agent is not a business case by itself. The business case is the improvement it can produce, the evidence that supports its output and the limits placed around its use.
For years, I have seen the same mistake across data, analytics and transformation programs. A team begins with a tool, runs a polished demonstration and searches for a problem afterward. The demonstration works because the data and questions were selected in advance. The production workflow fails because real data is incomplete, users behave differently and nobody agreed on who should review an incorrect answer.
Therefore, this guide offers a practical starting point for business leaders and beginners. It covers the main ways AI creates business value, a method for choosing the first project, suitable starting use cases for major functions and industries, and the security and responsible-AI controls that belong in the pilot from the start.
What AI can actually do for a business
In practice, most business applications of AI fit into four operating patterns. The technology may differ, but the job being done usually does not.
| AI pattern | What it does | Typical business example | Main failure to test |
|---|---|---|---|
| Retrieve and generate | Finds approved information, summarizes it or drafts new content | Policy assistant, account brief, service-response draft | Invented statements or missing sources |
| Classify and extract | Reads text, images or documents and assigns fields, categories or exceptions | Invoice extraction, complaint routing, contract-clause identification | Wrong category or missed exception |
| Predict and detect | Estimates an outcome or identifies an unusual pattern | Demand forecast, churn risk, equipment anomaly | Weak performance on new or underrepresented cases |
| Recommend and act | Proposes a decision or completes an approved action | Inventory recommendation, refund proposal, agent action | Excess authority, unsafe action or unclear accountability |
As a result, the first two patterns are often safer starting points because a person can inspect the source and correct the result before it affects a customer, employee or financial record. Prediction needs stronger historical data and monitoring. Action needs permission limits, approval rules, logs and a fast way to stop the system.
Why most lists of AI business use cases are incomplete
For example, popular articles offer dozens or hundreds of ideas. They are useful for brainstorming, but they often omit the questions that decide whether a project can work. What data is required? Is the result checkable? Where does it enter the workflow? Who owns the decision? What happens when the model is wrong?
Similarly, IBM describes successful enterprise use cases as frequent, well-defined tasks supported by trusted data, measurable outcomes and human oversight. Its examples include customer service, knowledge assistants, document processing, data analysis and software development. Those categories are sound, but each company still has to translate a category into one bounded workflow. See IBM: Generative AI use cases for enterprise.
However, in AI to ROI for Business Leaders, I make the same distinction between an interesting capability and an investable business case. The first should create curiosity. The second needs an owner, baseline, target, cost, adoption plan and stop condition.
Choose AI business use cases with four gates
First, make the use case pass four gates before comparing vendors or models. A weak answer at any gate is a reason to narrow the project or choose another one.

1. Outcome
To begin, name one result that should improve and record its current baseline. Good measures include handling time, forecast error, first-contact resolution, manual corrections, conversion rate, downtime, days to close and cost per completed case. “Improve productivity” is too vague unless the team defines which task, whose time and how it will be measured.
2. Evidence
Next, list the exact sources the system needs. Check their ownership, freshness, access rules and historical quality. A knowledge assistant should cite approved documents. Meanwhile, a prediction needs a reliable outcome label. Before selecting a document model, sample the formats and exception types.
3. Workflow
Then, name the people who will use the output and the moment when they will use it. An accurate answer that arrives after the decision has no value. A tool that adds another screen, another login or another queue may increase work. Observe the current process before designing the AI step.
4. Boundary
Finally, write down what the system may prepare, recommend, approve and execute. Name the reviewer and the decision owner. For a first pilot, I prefer systems that prepare evidence or flag exceptions while a person keeps authority over customer promises, hiring, payments, safety, legal interpretation and other consequential decisions.
A practical scoring method
Afterward, score each candidate from 1 to 5 on business value, data readiness, implementation feasibility, adoption fit and risk. Do not hide risk inside an average. A high-risk use case should receive a separate review even when its total score is attractive.
| Factor | Question | Evidence to collect |
|---|---|---|
| Business value | Does the problem occur often and affect a meaningful measure? | Volume, time, cost, errors, delay or lost revenue |
| Data readiness | Are the required sources available, permitted and dependable? | Source inventory, samples, quality checks and access approval |
| Feasibility | Can a bounded version be tested with current systems and skills? | Integration path, model test and delivery estimate |
| Adoption fit | Will the output appear where people already work? | User interviews, process map and named workflow owner |
| Risk | Could an error harm a person, disclose data or create an unauthorized action? | Impact review, decision boundary and control owner |
Overall, favor a frequent task with clear evidence and a reversible output. A glamorous use case with uncertain data and direct authority is a poor opening project.
When several use cases pass these gates and compete for the same budget, my AI prioritization framework converts each claim into net value after review time, exceptions and adoption, then tests whether the ranking holds.
Best starting AI business use cases by function
Specifically, the tables below are a starting map, not a promise that every company should build every item. Each row pairs a useful first scope with its data, measure and human limit.
Customer-facing and people functions
| Function | Good starting use case | Data required | Measure | Human boundary |
|---|---|---|---|---|
| Sales | Prepare an account brief with recent activity, open issues and cited sources | CRM activity, orders, service cases and approved account notes | Preparation time, usage and correction rate | Seller owns outreach, pricing and commitments |
| Marketing | Classify customer feedback and draft campaign variants from approved claims | Feedback, campaign history, product facts and brand rules | Review time, classification accuracy and test performance | Marketer approves claims, audience and publication |
| Customer service | Retrieve policy passages and draft a response for the agent | Current policies, product documentation and resolved cases | Handling time, first-contact resolution and correction rate | Agent owns the response, refund and exception |
| Finance | Prepare invoice or journal exceptions with supporting evidence | Transactions, master data, rules and prior resolutions | Review time, false positives and missed exceptions | Finance owner approves posting and payment |
| Human resources | Answer policy questions with citations and route unresolved cases | Approved policies, benefits material and case categories | Deflection, answer accuracy and escalation quality | HR reviews individual guidance and employment decisions |
Commercial and operational functions
| Function | Good starting use case | Data required | Measure | Human boundary |
|---|---|---|---|---|
| Procurement | Compare supplier bids and flag missing terms | Requests, bids, contracts, specifications and supplier records | Comparison time, omissions and reviewer acceptance | Buyer owns selection, negotiation and award |
| Supply chain | Explain forecast exceptions and prepare replenishment options | Demand, inventory, lead times, orders and constraints | Forecast error, stockouts, overrides and planner time | Planner approves changes and unusual allocations |
| Operations | Summarize shift events and prioritize maintenance inspection | Sensor readings, work orders, alarms and maintenance history | Detection lead time, false alarms and downtime | Qualified staff make safety and shutdown decisions |
Professional, technical and leadership functions
| Function | Good starting use case | Data required | Measure | Human boundary |
|---|---|---|---|---|
| Legal and compliance | Identify clauses or obligations for lawyer review | Contracts, approved clauses, policies and regulatory material | Review time, recall and missed high-risk clauses | Lawyer interprets the obligation and gives advice |
| IT and data | Summarize incidents, propose tests or explain approved metadata | Logs, tickets, runbooks, lineage and code repositories | Resolution time, test pass rate and accepted suggestions | Engineer approves production changes and access |
| Product | Cluster feedback and connect themes to source comments | Research notes, support cases, reviews and product telemetry | Analysis time, theme stability and source coverage | Product owner decides priority and roadmap |
| Executive team | Prepare a cited operating review that highlights exceptions | Certified metrics, plans, risks and meeting actions | Preparation time, data disputes and action closure | Leaders interpret causes and make decisions |
Why knowledge retrieval is often a good first project
For instance, functions with many policies, manuals, contracts or procedures can often begin with a source-grounded assistant. The pilot can be limited to an approved document set, every answer can show its citation and uncertain questions can be routed to a specialist. This applies to HR, service, legal operations, IT support, sales enablement and regulated procedures.
However, the boundary matters. Loading documents into a model does not train it to interpret every case correctly. Documents can conflict, expire or omit local exceptions. A useful assistant retrieves evidence and states uncertainty. It does not pretend to be the policy owner.
Why exception preparation is often better than full automation
By contrast, in finance, procurement, supply chain and operations, the strongest first project often prepares the unusual cases for review. The system can gather records, apply rules, summarize history and explain why a case was flagged. The reviewer sees fewer routine items and more relevant evidence. This design creates measurable time savings while preserving approval authority.
AI business use cases by industry
Product and financial industries
| Industry | Practical starting point | Measure | Boundary or warning |
|---|---|---|---|
| Manufacturing | Prioritize equipment inspections from sensor and maintenance history | Lead time, false alarms and unplanned downtime | Do not let an untested model make safety shutdown decisions |
| Retail | Summarize reviews or improve product discovery using catalog facts | Search success, conversion and return reasons | Check product claims, availability and recommendation bias |
| Banking | Retrieve policies for service staff or prepare analyst research | Research time, citation accuracy and handling time | Keep lending, fraud disposition and customer action under governed review |
| Insurance | Extract claim documents and prepare a file summary | Cycle time, extraction accuracy and reopened cases | Adjuster owns coverage interpretation and settlement |
Health and scientific industries
| Industry | Practical starting point | Measure | Boundary or warning |
|---|---|---|---|
| Healthcare | Search approved clinical knowledge or draft administrative summaries | Retrieval time, citation accuracy and clinician corrections | Clinician owns diagnosis and treatment; protect health data |
| Life sciences | Search literature and regulatory documents with traceable sources | Research time, source coverage and expert acceptance | Scientists validate claims, methods and regulated submissions |
Infrastructure and service industries
| Industry | Practical starting point | Measure | Boundary or warning |
|---|---|---|---|
| Logistics | Score delivery risk or summarize shipment exceptions | On-time delivery, successful delivery and planner time | Provide fallback rules for missing or delayed signals |
| Energy and utilities | Prioritize field inspection from asset history and alarms | Detection lead time, truck rolls and false positives | Qualified operators retain control of safety actions |
| Professional services | Find prior work, extract obligations and draft a cited first version | Search time, reuse and reviewer corrections | Protect client separation, privilege and confidential material |
| Government | Classify public requests or retrieve approved service information | Response time, routing accuracy and accessibility | Provide explanation, appeal and non-digital service options |
| Education | Retrieve course material or draft feedback for instructor review | Instructor time, citation accuracy and student outcomes | Teacher owns assessment; protect student data |
Real examples and the lesson behind each one
In addition, public case studies can show what is possible, but vendor-reported results should be treated as reference points. Your baseline, data and operating model will differ.
- Deutsche Bank: DB Lumina helps financial analysts prepare research reports and notes while meeting data privacy requirements. This pattern speeds up research while analysts remain responsible for conclusions.
- Best Buy: Vertex AI condenses product reviews into customer-facing insights, and its contact-center implementation prepares real-time conversation summaries. Here, AI summarizes large text volumes while agents can review the source content.
- Mayo Clinic: Vertex AI Search helps scientific researchers retrieve information across a large clinical data environment. The useful pattern is governed search that creates value before the system receives authority to act.
- UPS Capital: DeliveryDefense Address Confidence gives shippers a score for successful-delivery likelihood. In this case, the model presents a decision signal while the shipper controls the response.
- Volkswagen of America: The myVW assistant helps drivers query owner manuals and interpret dashboard indicators using text and images. The transferable idea is to ground answers in a bounded product knowledge base.
For reference, these examples are described in Google Cloud: Real-world generative AI use cases. They are useful patterns, not automatic project choices.
Match controls to the level of AI responsibility
For this reason, a system that summarizes approved documents does not need the same controls as an agent that can issue a refund, change a purchase order or modify production data. Control strength should rise with autonomy and consequence.
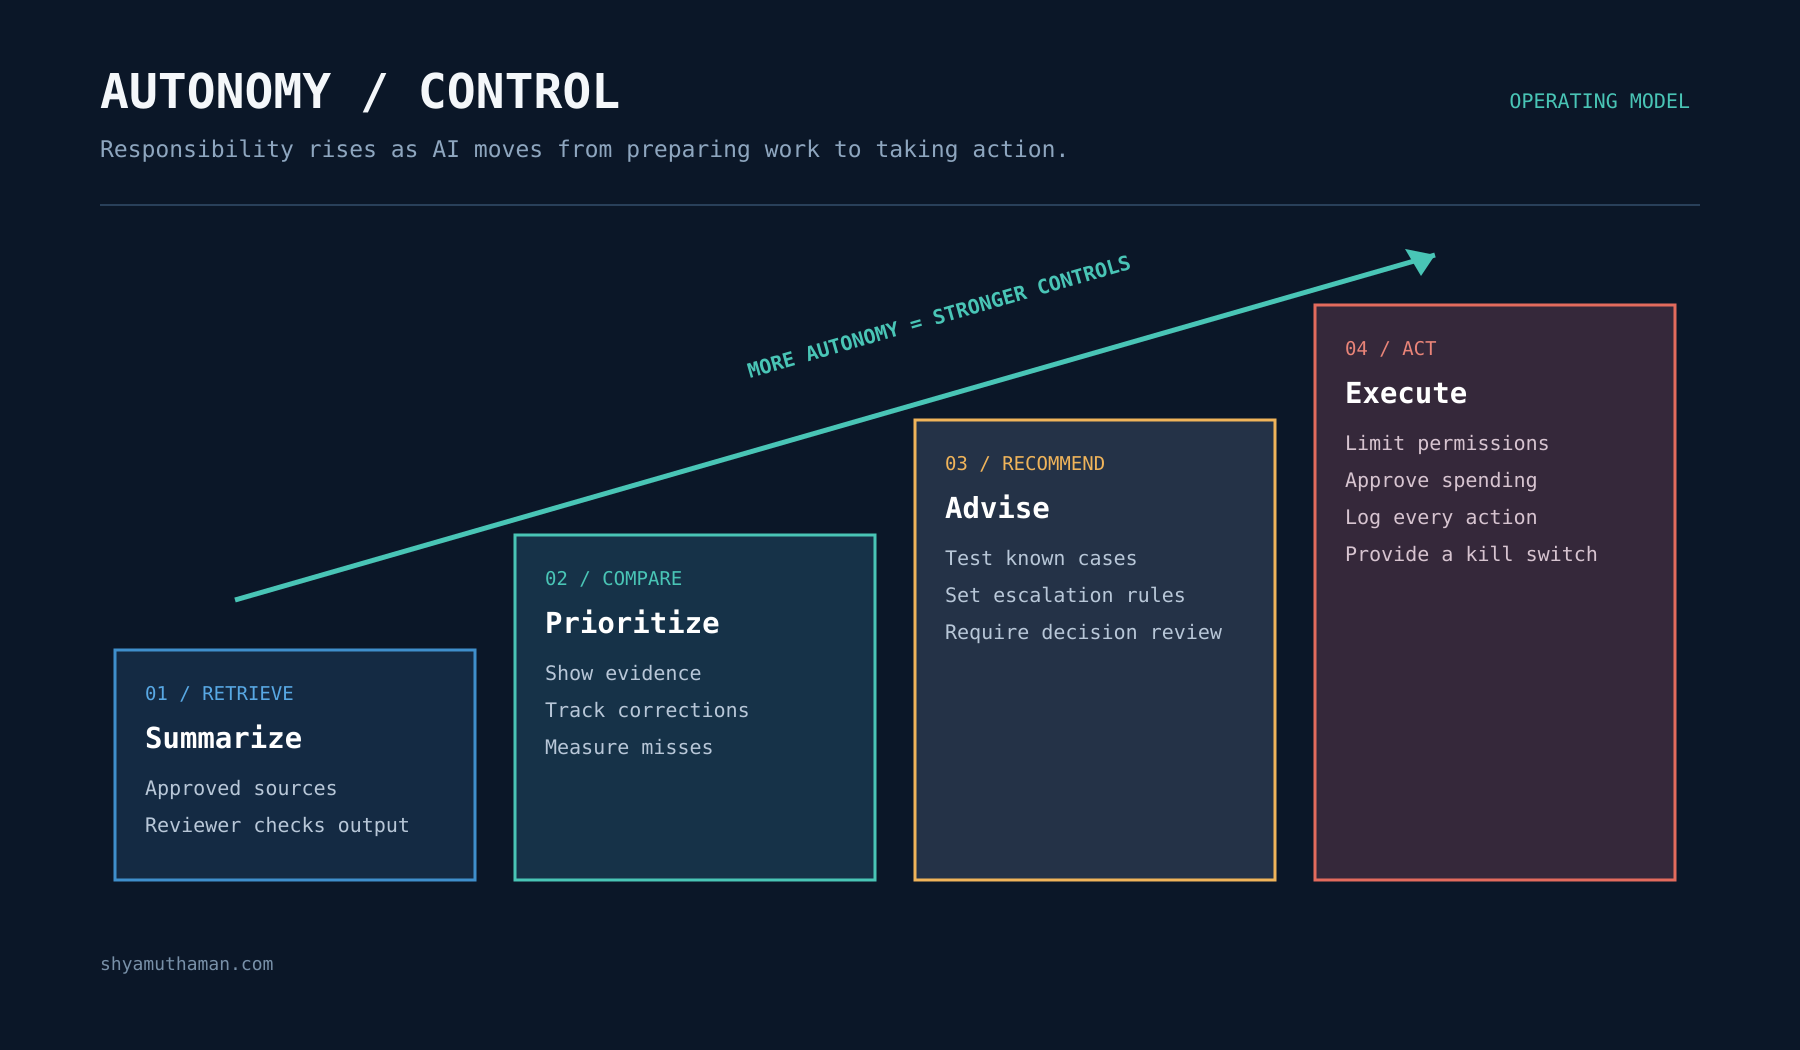
Initially, at the retrieval level, approved sources, citations and reviewer feedback may be enough for a bounded pilot. Recommendation systems need test cases, performance thresholds and escalation rules. Systems that act need narrow permissions, transaction limits, approval checkpoints, tamper-resistant logs, incident handling and a kill switch.
Even so, human review is useful only when the reviewer has enough time, information and authority to disagree. A rubber-stamp approval screen does not transfer accountability back to a person. Measure how often reviewers change the output, how long review takes and whether they can see the evidence behind it.
Security, responsible AI and ethics belong inside the pilot

Data and privacy
First, use approved data only. Define what may enter prompts, indexes, logs and feedback stores. Set retention and deletion rules. Mask personal or confidential data where it is not needed. Confirm whether the provider uses submitted content for model improvement and where the data is processed.
Access and security
Next, give the system the smallest permissions needed for the task. Keep secrets outside prompts and retrieved content. Test prompt injection, malicious documents, unsafe tool calls and data leakage between users. The OWASP Top 10 for LLM and generative AI applications covers prompt injection, sensitive-information disclosure, improper output handling, excessive agency, misinformation and other common risks.
Quality and fairness
Meanwhile, create a test set from real cases, including rare, difficult and intentionally adversarial examples. Measure factual accuracy, citation support, false positives, false negatives and performance across relevant groups. Re-test when the model, prompt, source documents or business rules change.
Human accountability
Also, name the system owner, data owner, workflow owner, reviewer and incident contact. Tell users when they are interacting with AI. Provide a way to correct records, contest consequential outcomes and reach a person. In employment uses, accessibility and discrimination risks deserve specific review. The U.S. Equal Employment Opportunity Commission guidance on AI and the ADA explains risks when software or algorithms assess applicants and employees.
Operations
Finally, log inputs, retrieved sources, outputs, model versions, approvals and actions at a level appropriate to privacy rules. Monitor quality, cost, latency and incidents. Define rollback, outage and kill-switch procedures. A pilot is an operating service, even when only a small group uses it.
For further guidance, the NIST AI Risk Management Framework provides a voluntary structure for managing risks to people, organizations and society. NIST also publishes a Generative AI Profile for risks specific to generative systems.
How to run the first AI pilot
- Write the problem statement. Name the user, current task, baseline, target and business owner.
- Set the boundary. Choose one workflow, a defined user group, approved data and actions the system cannot take.
- Build the evaluation set first. Collect normal cases, edge cases, known failures and cases where the correct response is to escalate.
- Test offline. Compare output with known answers before placing it in a live process. Record errors rather than discussing only good examples.
- Run with human review. Capture acceptance, corrections, review time, incidents and user feedback.
- Compare with the baseline. Include operating cost, review effort and correction work in the result.
- Decide whether to scale, revise or stop. A stopped pilot can be a good result when it prevents a weak system from reaching production.
Measure value without hiding the correction burden
| Measure | Simple calculation | Why it matters |
|---|---|---|
| Net time saved | Old task time minus AI task time minus review and correction time | Prevents gross automation claims from hiding manual cleanup |
| Acceptance rate | Outputs accepted without material change divided by outputs reviewed | Shows practical usefulness |
| Correction rate | Outputs materially changed divided by outputs reviewed | Reveals hidden quality work |
| Supported-answer rate | Answers backed by valid evidence divided by answers tested | Tests grounding and traceability |
| Cost per completed case | Model, platform, integration and review cost divided by completed cases | Supports an honest ROI comparison |
| Business outcome | Change in the selected operational measure versus baseline | Connects AI activity to business value |
Therefore, I would stop or redesign the pilot when the source data cannot support the requested answer, reviewers cannot detect important errors, correction work removes the time benefit, adoption depends on forcing another disconnected tool, incidents exceed the agreed threshold or the business owner will not accept accountability.
A good first business case
In short, a good first business case can be stated in one paragraph: who has the problem, how often it occurs, what the current baseline is, what data supports the task, what the AI will prepare, what a person will still decide, how success will be measured and what would cause the project to stop.
Based on that experience, my preference is to start with a bounded, frequent and checkable task. Build trust through visible evidence and measured corrections. Add authority only after the organization has proved that it can operate the lower-risk version. This is consistent with the operating approach in The Data-Driven Executive, where decisions begin with reliable information and clear ownership, and with AI to ROI for Business Leaders, where value is measured in business results rather than demonstration quality.
Frequently asked questions about AI business use cases
What is the best first AI use case for a small business?
For a small business, choose a repeated task with approved source material and easy human review. For example, the system could draft responses from a product knowledge base, classify customer inquiries or summarize feedback. However, avoid a first project that can send money, make employment decisions or change customer records without approval.
Should a company begin with generative AI or predictive AI?
In practice, choose based on the problem and data. Generative AI fits retrieval, summarization, extraction and drafting. Predictive AI fits outcomes such as demand, churn, fraud risk or equipment failure when dependable historical labels exist. Some workflows use both.
How many AI use cases should a company pilot?
As a rule, start with one bounded workflow or a very small portfolio that shares the same data and control pattern. Otherwise, unrelated pilots spread data, security, evaluation and adoption work across teams before the operating method is proven.
What data is needed for an AI pilot?
Of course, the answer depends on the use case. Knowledge assistants need current, approved documents and access metadata. Predictive models need historical features and a trustworthy outcome label. Document processes need representative files and known exceptions. Therefore, begin with a source inventory and real samples.
What are you trying to build, what data do you have, and what is blocking you? Share the function, industry and workflow in the comments. I will use the details to suggest a suitable starting scope and the boundary I would place around it.